Persian Speech-to-Text Engineered for Enterprise Telephony & Contact Centers
Most generic speech-to-text models are trained on studio-quality podcasts or clean microphone audio, resulting in catastrophic accuracy drop-offs when exposed to degraded 8kHz telecommunication lines. ZharfAva has built and calibrated its ASR layer specifically for the harsh acoustic realities of real-world enterprise telephone calls.
Acoustic Realities of Enterprise Telephony: Why Telecom Audio Demands Specialized Models
Bandwidth-Constrained 8kHz
PSTN and cellular networks truncate high frequencies, muffling fricative and sibilant Persian consonants. Specialized acoustic acoustic compensation models are essential to prevent word loss.
Overlapping Speech & Cross-Talk
During heated customer escalations, agent and caller speak concurrently. Accurate multi-speaker diarization is vital to maintain temporal transcript ordering.
IDs, Numeric Sequences & Jargon
National identification numbers, banking IBANs, alphanumeric tracking codes, and industry-specific lexicons require strict language model adaptation.
Key Capabilities of the ZharfAva ASR Engine
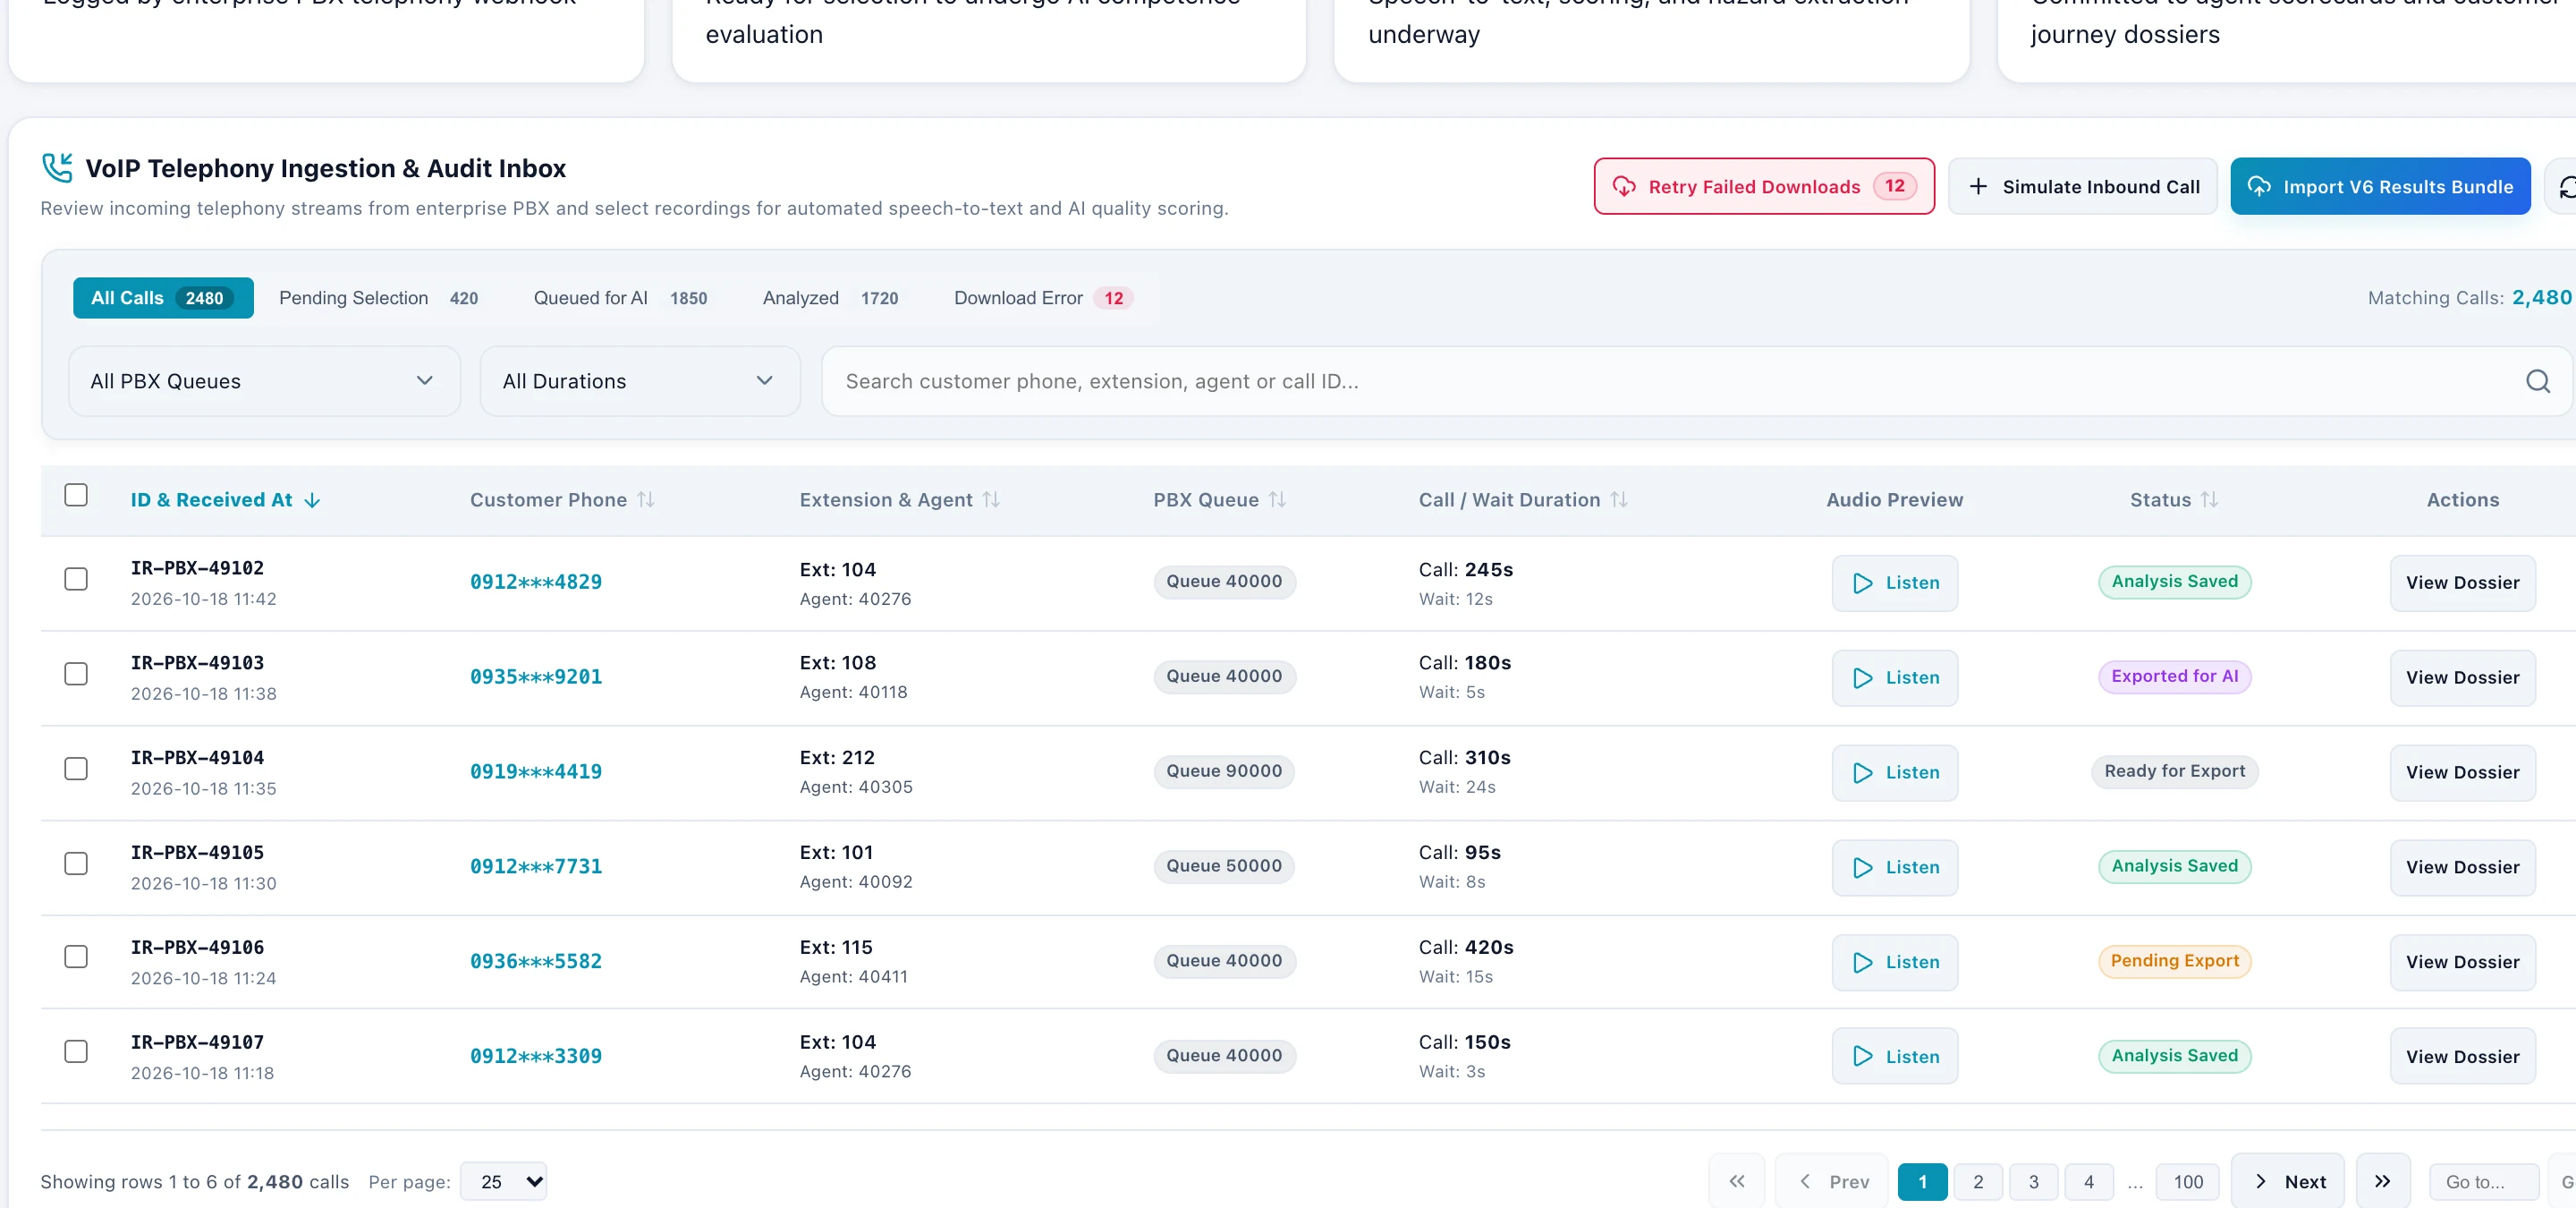
Transcription in ZharfAva serves as the high-accuracy foundation for downstream conversation intelligence pipelines:
Transcription is the Starting Point, Not the Final Destination
Having text transcripts alone does not solve enterprise challenges—no executive has the bandwidth to read millions of lines of conversation. ZharfAva’s core enterprise value lies in instantly feeding transcripts into automated quality scoring, intent detection, and strategic trend clustering.
Benchmark Accuracy on Your Telephony Recordings
Evaluate Persian speech recognition accuracy on your organization’s proprietary telephony streams.